A Stimarium Dossier
The standard human genome is mostly one person
When a lab reads someone's DNA, it lines up millions of short fragments against a standard human genome, a reference copy of a full set of human DNA. That standard is stitched together from more than 20 people, and one of them makes up most of it. DNA that differs from that one person is easier to misread or miss.
What’s known, what’s not: Known, Our read, OpenCorrection, 22 October 2026: We had said both cited accounts put the main donor's share of the reference at about 70 percent. One gives about 65 percent and the other 70, so we now say 65 to 70. How we handle corrections
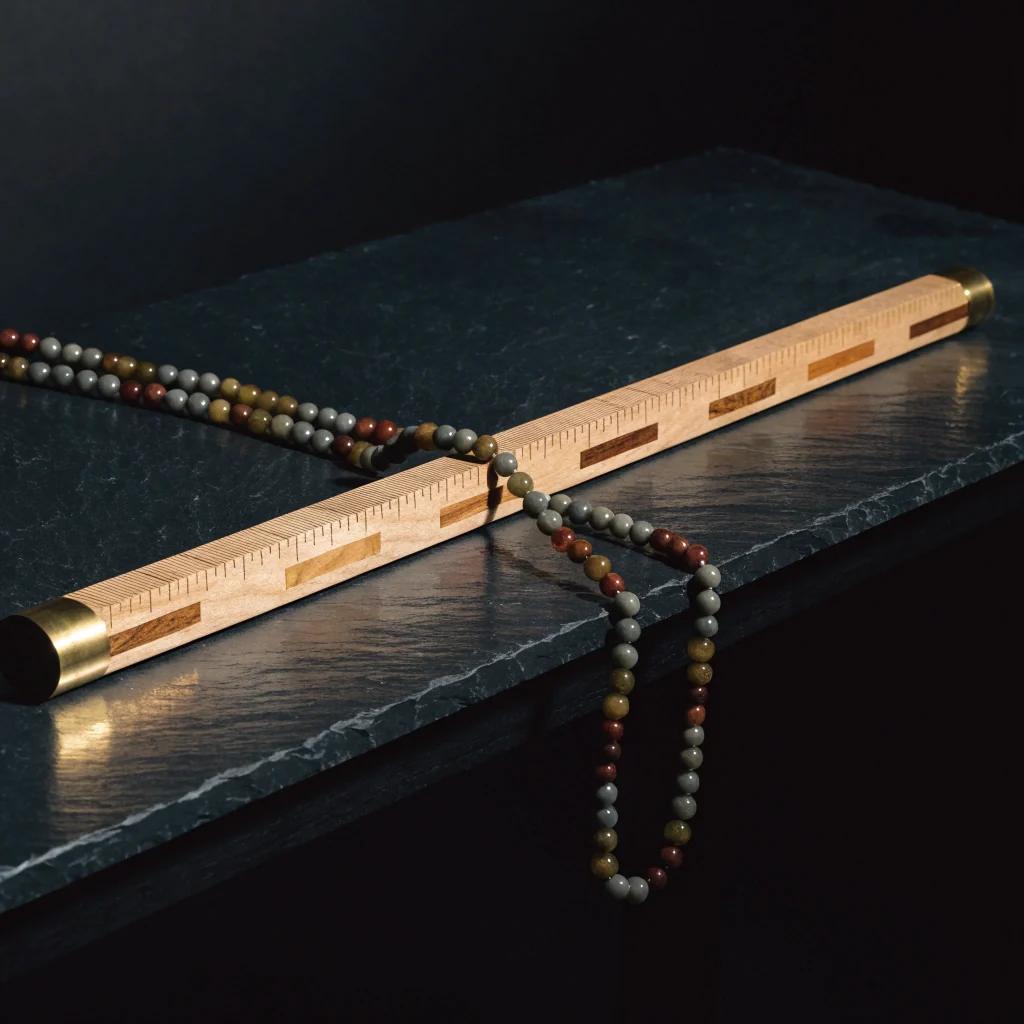
Every genome is read against another genome
When a lab reads someone's DNA, the machine produces millions of short fragments, each a few hundred letters long. Software places each fragment by finding where it matches a standard human genome, the reference. [S04]
Wherever a person's DNA differs from the reference, the software has to decide whether it is seeing a real variant or a reading error. A difference from the standard reads as a variant, or as noise. [S04, S05]
So the reference works as a ruler: every other genome is measured against it. [S01]
A difference from the standard reads as a variant, or as noise.
A standard stitched from about 20 people, mostly one
The current reference, called GRCh38, is a composite of DNA from more than 20 people. Across most of its length it carries the sequence of a single person. [S01, S04]
The cited 2019 and 2022 accounts put that person's contribution at about 65 to 70 percent of the reference sequence. [S01, S04]
Where that person had rare variants or missing stretches, the standard has them too. Ballouz, Dobin and Gillis argued in 2019 that it represents one individual more closely than an average human. [S04]
About 300 million letters nobody was looking for
In 2019, Rachel Sherman and colleagues assembled DNA from 910 people of African descent and looked for sequence the reference lacks. They found about 300 million letters, roughly a tenth of a genome's length, absent from the standard. [S03]
DNA missing from the reference can be missed by standard mapping pipelines. These pipelines are the software steps that match DNA fragments to the reference. Some fragments fail to align, while others can be placed incorrectly; assembling unmapped reads offers one way to recover missing sequence. [S03, S05]
A 2026 preprint, a study shared before peer review, benchmarked 30 bladder-tumor exomes. There, a pangenome reference improved the accuracy of detecting single-letter tumor mutations by an average of about 20 percent for samples from people of East Asian ancestry, with marginal gains for European ancestry. A separate set of 29 lung tumors also showed improved precision, especially for East Asian ancestry. [S07]
DNA missing from the reference can be missed by standard mapping pipelines.
Forty-seven people instead of one
In 2023 the Human Pangenome Reference Consortium released a draft pangenome: genome assemblies from 47 genetically diverse people, stored together so software can match DNA fragments against all of them. The assemblies cover more than 99 percent of each genome's expected sequence and separate the two inherited chromosome sets. [S02]
It added 119 million letters of sequence that vary between people and that GRCh38, the older reference, lacked. In tests using short DNA fragments, the pangenome cut errors in spotting small differences, such as a single changed letter, by 34 percent. It also detected 104 percent more large structural variants per haplotype, one inherited set of chromosomes. These include long stretches of DNA that are rearranged, duplicated, inserted or missing. Both gains were measured against workflows using GRCh38. [S02]
Tools that build a personalized reference for each sample now report further gains. The direction is consistent: the closer the ruler is to the person, the fewer the errors. [S06]
A skewed copy that still worked
The single-person reference did its job. Nearly every human genetics finding of the past two decades was made against it, and for most of the genome it reads most people well. [S01, S04]
Its errors were not random. They fell where a person's DNA differs from the reference, and studies find them spread unevenly across ancestries. [S03, S07]
A standard reflects whoever was available to build it. This one was skewed and still enabled genetic analysis, and the fix was to include more people.
A standard reflects whoever was available to build it.
Think with the idea.
Take me sideways
A spell checker built from one writer's vocabulary flags everyone else's correct words as typos, exposing the limits of its dictionary.
Analogy.Challenge it
The reference reads most of most people's DNA correctly, and older references were already mosaics. The cited accounts put the main donor's share at about 65 to 70 percent. The size of the bias varies by method and ancestry.
Scope warning.Trace it
Set it beside the faces rebuilt on skulls. In both, a standard built by particular people becomes the default for everyone, until someone measures who it fails.
Cross-domain synthesis, not a finding of the cited studies.Take it with you
When a genetic test reports no variant found, it is worth asking what the test was able to look for, and whose DNA its reference was built from.
Reflection prompt, not medical advice.What’s known, what’s not
↑ Back to where you were- The standard human reference genome merges DNA from more than 20 people, and one person makes up most of it. [S01]
- DNA from 910 people of African descent held about 300 million letters missing from the reference. [S03]
- Compared with the older reference, a 47-person pangenome reduced errors in finding small DNA differences by 34 percent in short-fragment tests. [S02]
We think a reference genome reflects the DNA of the people who donated to it, mostly one person. DNA that differs from the reference is easier to misread or miss.
- How many disease-linked variants are still hidden in DNA the old reference never contained?
- Will one pangenome, a DNA reference built from many people, stay current as more populations are sequenced?
What the three labels meanClose explanations
Known marks what the cited evidence directly supports, including what named researchers argue.
Our read is Stimarium’s own interpretation of that evidence.
Open marks a question the cited evidence can’t answer yet, or a possibility we are raising ourselves.